
Appearance
Build a RAG pipeline - answers with citations
The real problem
Employees ask Northwind's helpdesk about leave. A bare model invents numbers. A hand-written flow (search, paste into a prompt, hope) works in a demo, then fails on follow-ups ("and for my second child?"), on questions the policy does not cover, and when someone types a customer's card number into the chat.
A RAG pipeline (retrieval-augmented generation) is that flow made explicit and testable: each stage is visible, has a setting, and reports what it did.
The idea in one minute
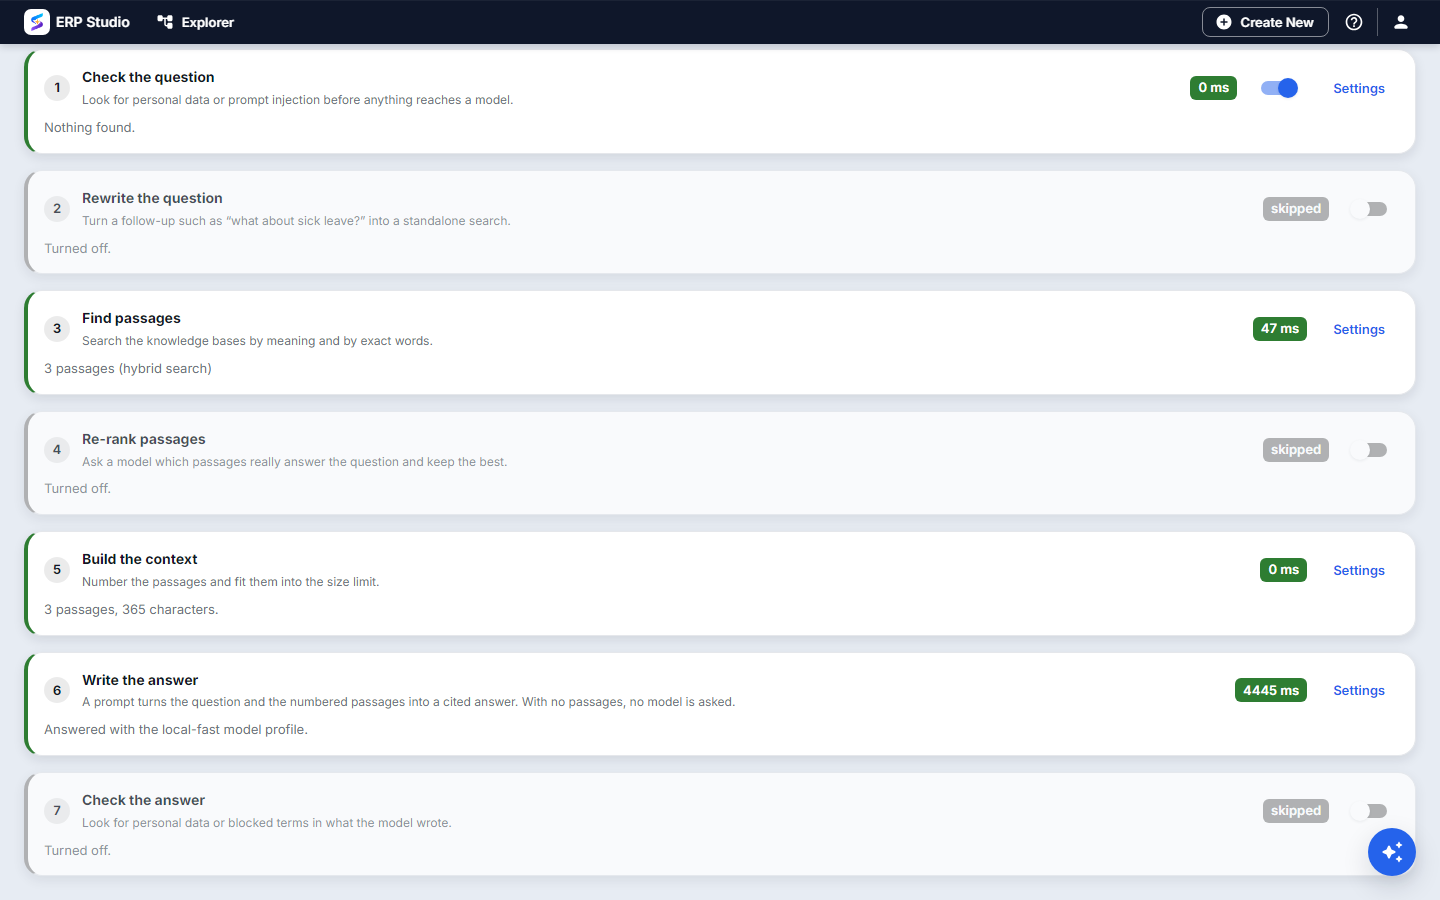
Seven stages; only retrieve and generate are required.
| Stage | What it does | Key settings |
|---|---|---|
| Input guard | Checks the question | checks (pii, injection, blockedTerms), action (flag, mask, block), max length |
| Rewrite | Turns a follow-up into a standalone search | on/off, profile |
| Retrieve | Searches knowledge bases | knowledge bases, mode (HYBRID, VECTOR, KEYWORD), top K, threshold |
| Rerank | A model reorders the best passages | on/off, profile, top N |
| Context | Packs passages into a size budget | max characters |
| Generate | Fills the answer prompt and calls the model | prompt (from the library) or inline templates, profile |
| Output guard | Checks the answer | same checks as the input guard |
If nothing relevant is found, the pipeline returns its no-answer text instead of letting the model guess. Like prompts, a pipeline has versions and labels.
Designer path (Studio)
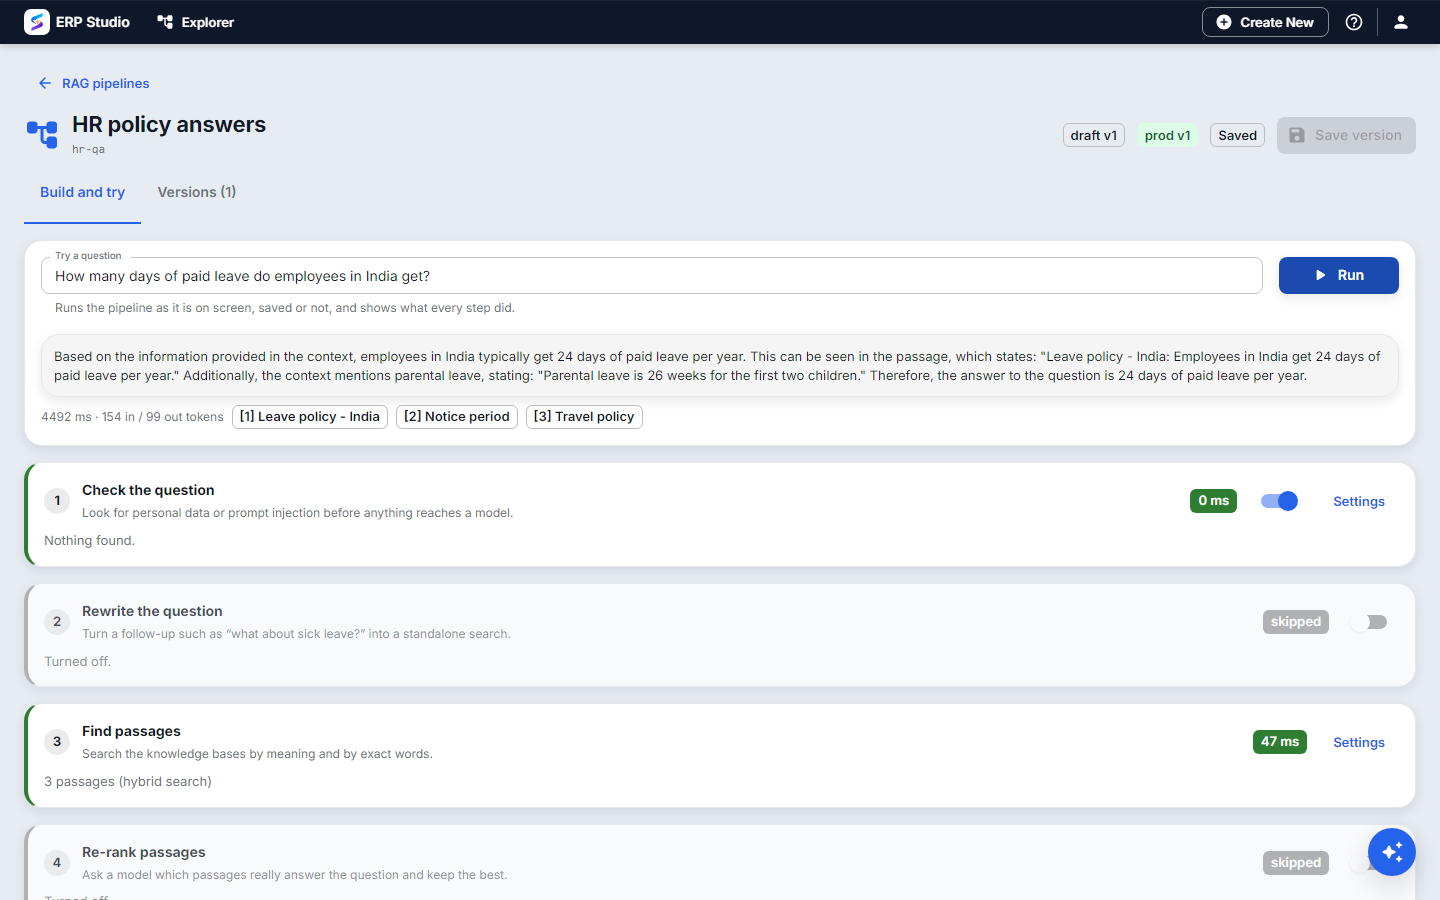
- Prepare a knowledge base (guide) and, optionally, an answer prompt.
- Open AI Studio > RAG pipelines > New. Code
hr-qa. A starter definition is filled in. - On Build and try:
- Input guard: turn on
injectionandpii, actionmask(so a pasted card number never reaches the model). - Rewrite: on, so "and for my second child?" becomes a full question.
- Retrieve: pick
hr-policies, mode Hybrid, top K 5, threshold 0.3. - Generate: choose the answer prompt and label, or keep the inline template that says "Answer only from the context. Cite passages as [1], [2]."
- No-answer text: "I could not find this in the HR policies. Please contact HR."
- Input guard: turn on
- Type a real question and press Run. You get the answer, the citations, and a stage report showing what each stage received and returned, its time and any model tokens.
- Ask something the policy does not cover. The no-answer text must appear, not an invented answer.
- Save as new version, put the label prod on it.
Developer path
metadata/rag/hr-qa.json:
json
{
  "pipelineCode": "hr-qa",
  "name": "HR policy answers",
  "definition": {
    "inputGuard": { "enabled": true, "checks": ["injection", "pii"], "action": "mask" },
    "rewrite": { "enabled": true },
    "retrieve": { "knowledgeBases": ["hr-policies"], "mode": "HYBRID", "topK": 5, "threshold": 0.3 },
    "context": { "maxChars": 6000 },
    "generate": { "profileCode": "default" },
    "outputGuard": { "enabled": true, "checks": ["pii"], "action": "flag" },
    "noAnswerText": "I could not find this in the HR policies. Please contact HR."
  },
  "labels": ["prod"]
}
bash
erp schema validate spk-assembly/metadata/rag/hr-qa.json --schema ai-rag-pipeline
erp plugin op ai-rag-run --code hr-qa --label prod --question "How many leave days do I get?"
From code, the pipeline is just a model name; citations come back in a top-level citations field:
python
from app.ai import ask
result = ask("hr-qa", "How many leave days do I get?")
print(result["answer"], result["citations"])
POST /api/v1/ai/rag/hr-qa/run { "question": "...", "label": "prod" } -> answer, citations, stagesInside a workflow use the ai.rag step (AI workflow nodes).
How to verify
- The answer quotes the number in the policy and cites
[1]with the document title. - The stage report shows retrieve returned passages and generate used them.
- An off-topic question returns the no-answer text and the report shows retrieve found nothing above the threshold.
- A question containing a card number reaches the model masked (check the guard stage report).
Common mistakes
- Threshold too high. Good passages are dropped and everything says "no answer". Lower it and look at the scores in the retrieval test.
- Threshold too low with a loose prompt. The model is handed noise and answers anyway; keep the "answer only from the context" rule.
- Rerank always on. It adds a model call to every question; turn it on only if the retrieval test shows the right passage is found but ranked low.
- Changing the pipeline without measuring. Score it with an evaluation first.
Not built
Streaming (the answer arrives whole) and a publish gate that blocks a label move on a failing evaluation.
Next
Agents - when the model needs to do things, not just answer.